
As enterprise AI deployments continue to evolve, organizations require infrastructures that can efficiently support a diverse range of inference workloads, from speech recognition and graph analytics to large language models (LLMs), agentic AI, and advanced reasoning applications. The latest MLPerf™ Inference v6.1 Datacenter benchmark reflects this rapid transformation by evaluating systems across some of today’s most relevant AI models and deployment scenarios.
QCT proudly participated in the latest MLPerf Inference v6.1 with a comprehensive set of submissions spanning CPU-based inference, PCIe accelerator platforms, and high-performance systems such as NVIDIA HGX B300. These submissions demonstrate QCT’s commitment to delivering optimized infrastructure solutions for every stage of the AI journey, enabling customers to select the architecture best suited to their performance, scalability, and operational requirements.
Through MLPerf Inference v6.1 participation, QCT highlights three distinct deployment approaches designed to address a broad spectrum of AI use cases.
QuantaGrid D75E-4U: CPU-Based AI Inference Platform Powered by Intel® Xeon® and Intel® AMX
QuantaGrid D75E-4U, powered by dual Intel® Xeon® 6788P processors with Intel® Advanced Matrix Extensions (Intel® AMX), demonstrates how modern CPU architectures continue to play a critical role in lightweight AI inference deployments. Designed for flexibility and efficiency, this configuration enables organizations to deploy AI workloads within existing x86 infrastructure environments while maintaining excellent performance.
For MLPerf Inference v6.1, QCT submitted the following workloads on the CPU-based platform:
- Llama 3.1 8B
- RGAT (Relational Graph Attention Network)
- Whisper
These benchmarks span large language models, graph neural networks, and speech recognition, showcasing the versatility of CPU-based inference for enterprise workloads.
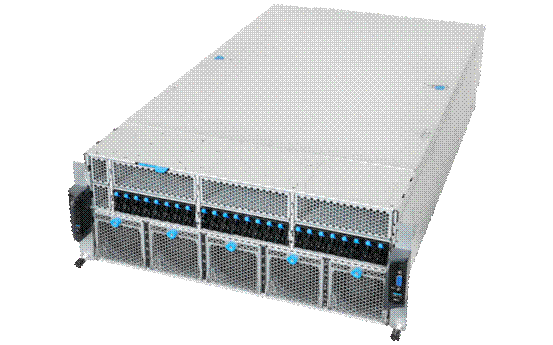
Fig. 1 QCT QuantaGrid D75E-4U
QuantaGrid D75E-4U with Intel® Arc™ Pro B70 GPUs
QCT also demonstrated the flexibility of the QuantaGrid D75E-4U platform through a PCIe accelerator-based configuration featuring four Intel® Arc™ Pro B70 GPUs.
Built to provide efficient AI acceleration while maintaining deployment flexibility, this configuration offers customers an additional pathway to improve inference performance for targeted AI workloads. By supporting multiple accelerator options, the D75E-4U enables organizations to align infrastructure investments with evolving AI requirements and operational goals.
For MLPerf Inference v6.1, this configuration was submitted with:
- Llama 3.1 8B
- Whisper
These workloads highlight the platform’s ability to efficiently accelerate both large language models and speech AI applications using PCIe-based accelerator technology.
QuantaGrid D75H-10U: Built for Frontier AI Based on NVIDIA HGX B300 System
At the high-performance end of QCT’s AI portfolio, the QuantaGrid D75H-10U delivers breakthrough performance for large-scale AI inference and training environments.
Powered by dual Intel® Xeon® 6 processors and featuring eight NVIDIA Blackwell Ultra GPUs in an SXM-based architecture connected as one with NVIDIA NVLink, the D75H-10U is purpose-built for hyperscale AI deployments requiring exceptional throughput, memory bandwidth, and multi-GPU scalability. The platform supports next-generation networking technologies and is optimized for the most demanding AI applications, including agentic AI, reasoning models, and large-scale LLM deployments.
QCT submitted the following MLPerf Inference v6.1 workloads on the QuantaGrid D75H-10U:
- Llama 2 70B (99%)
- DeepSeek-R1
- Whisper
- Qwen3-VL-235B-A22B
- GPT-OSS-120B
These models represent some of the most advanced AI applications being deployed today, covering language models, vision-language AI, speech processing, and reasoning-focused inference workloads. Their inclusion demonstrates the QuantaGrid D75H-10U’s ability to support emerging enterprise and cloud AI services at scale.
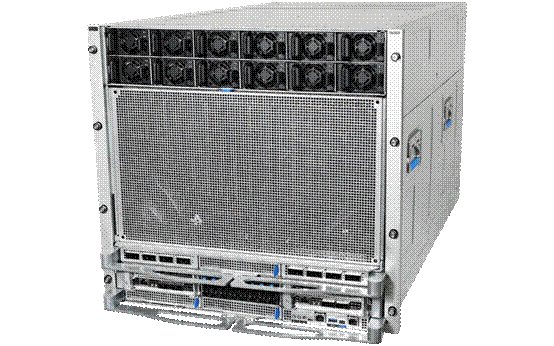
Fig. 2 QCT QuantaGrid D75H-10U
Enabling the Next Generation of Enterprise AI
QCT’s participation in MLPerf Inference v6.1 reflects their ongoing commitment to helping customers confidently deploy AI infrastructure optimized for real-world applications. By offering solutions ranging from CPU-based inference to PCIe accelerator systems and NVIDIA Blackwell Ultra platforms, QCT empowers organizations to build AI environments that balance performance, scalability, efficiency, and total cost of ownership.
As enterprises continue to embrace agentic AI, reasoning models, and speech AI, QCT remains focused on delivering the infrastructure foundation necessary to accelerate innovation and enable AI at scale.
For complete MLPerf Inference v6.1 benchmark results, visit the MLCommons MLPerf Inference Datacenter Benchmark Website.